🧪 VelsTech Lab Spark-X2.5 4B is a brand-new 4.1B architecture – so new that my llama.cpp build refused to load it (unknown model architecture: 'spark2_5'). After updating and rebuilding, I ran all three quants – BF16, Q8_0 and Q4_K_M – side by side on the RX 6800M. The result is not the usual "smaller is faster" story: Q8_0 wins prompt processing, Q4_K_M wins generation, and full-precision BF16 loses a quality task to both of them.
LLM VRAM Calculator – do the weights plus your context fit your VRAM? · GPU AI Performance Calculator – what tok/s to expect before you run.
Open calculators →Every number below – throughput, VRAM, GPU/CPU utilisation, temperature, power, and the context-fit estimate – was captured with benchscope, a llama-bench wrapper I built for exactly this kind of test. MIT licensed, runs anywhere llama-bench runs.
benchscope on GitHub →The test rig
- Machine: ASUS ROG Strix G513QY · Ryzen 9 5900HX (8C/16T) · AMD RX 6800M 12GB (RDNA2, mobile) · 32 GB RAM · 2 TB NVMe
- OS: Ubuntu 26.04.1 LTS (Wayland) · ROCm · llama.cpp rebuilt from current master for
spark2_5support (see llama.cpp guide),n_threads=8 - Models:
Spark-X2.5-4B.gguf(BF16, 7.66 GiB) ·Spark-X2.5-4B-Q8_0.gguf(4.07 GiB) ·Spark-X2.5-4B-Q4_K_M.gguf(2.42 GiB) – 4.1B params, 36 layers, 1M native context - Every run: full GPU offload,
-p 512 -n 128 -r 3, f16 KV cache, one bench process per test so prompt and decode get isolated telemetry
How we ran it
python3 benchscope.py --per-test \
  --llama-bench-bin ./build/bin/llama-bench \
  --out-json bench.json --timeseries bench.csv --out-png bench.png -- \
  -m ~/models/Spark-X2.5-4B-Q4_K_M.gguf -p 512 -n 128 -r 3
Same command for all three files, only -m changes. (benchscope sets the ROCm library path itself, so no LD_LIBRARY_PATH export dance.)
What we measured
Metric               BF16              Q8_0              Q4_K_M
──────────────────────────────────────────────────────────────────
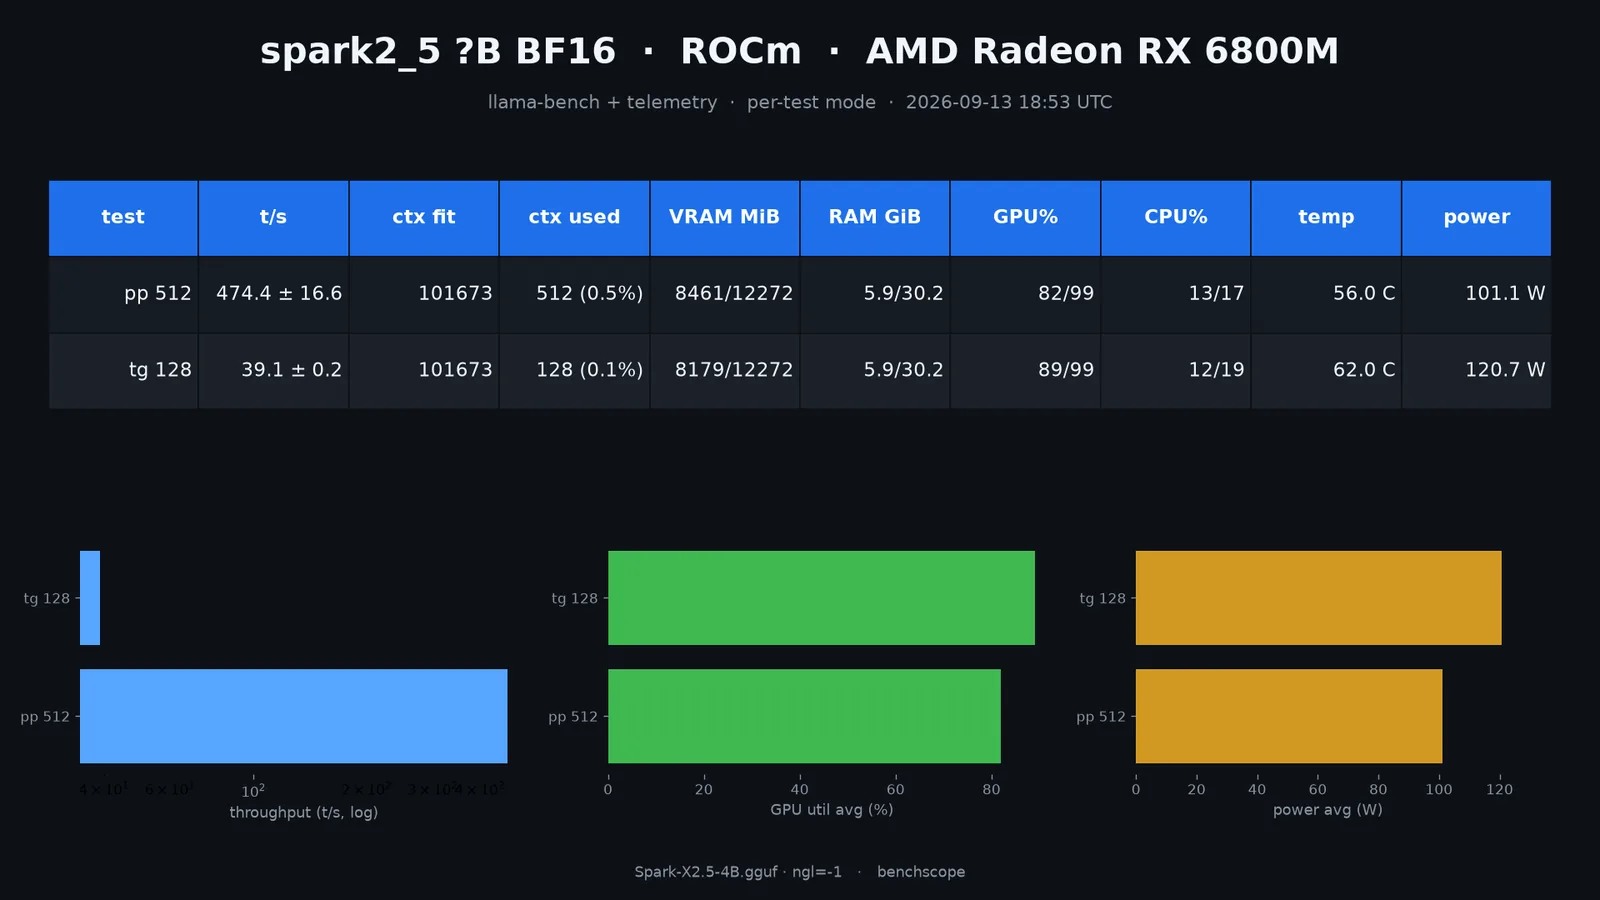
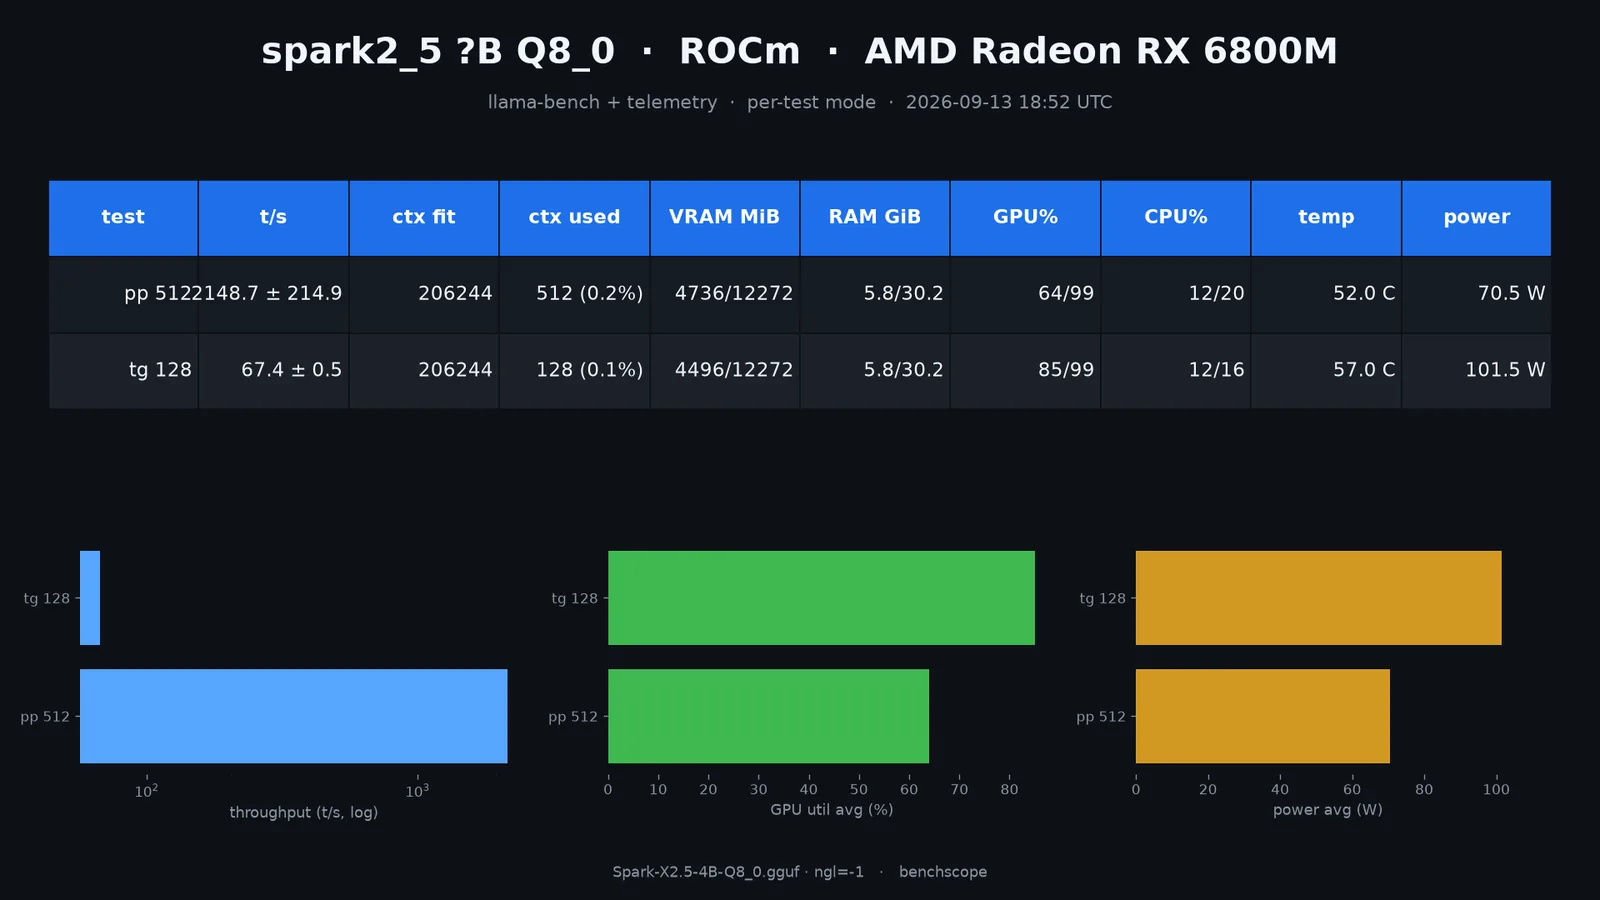
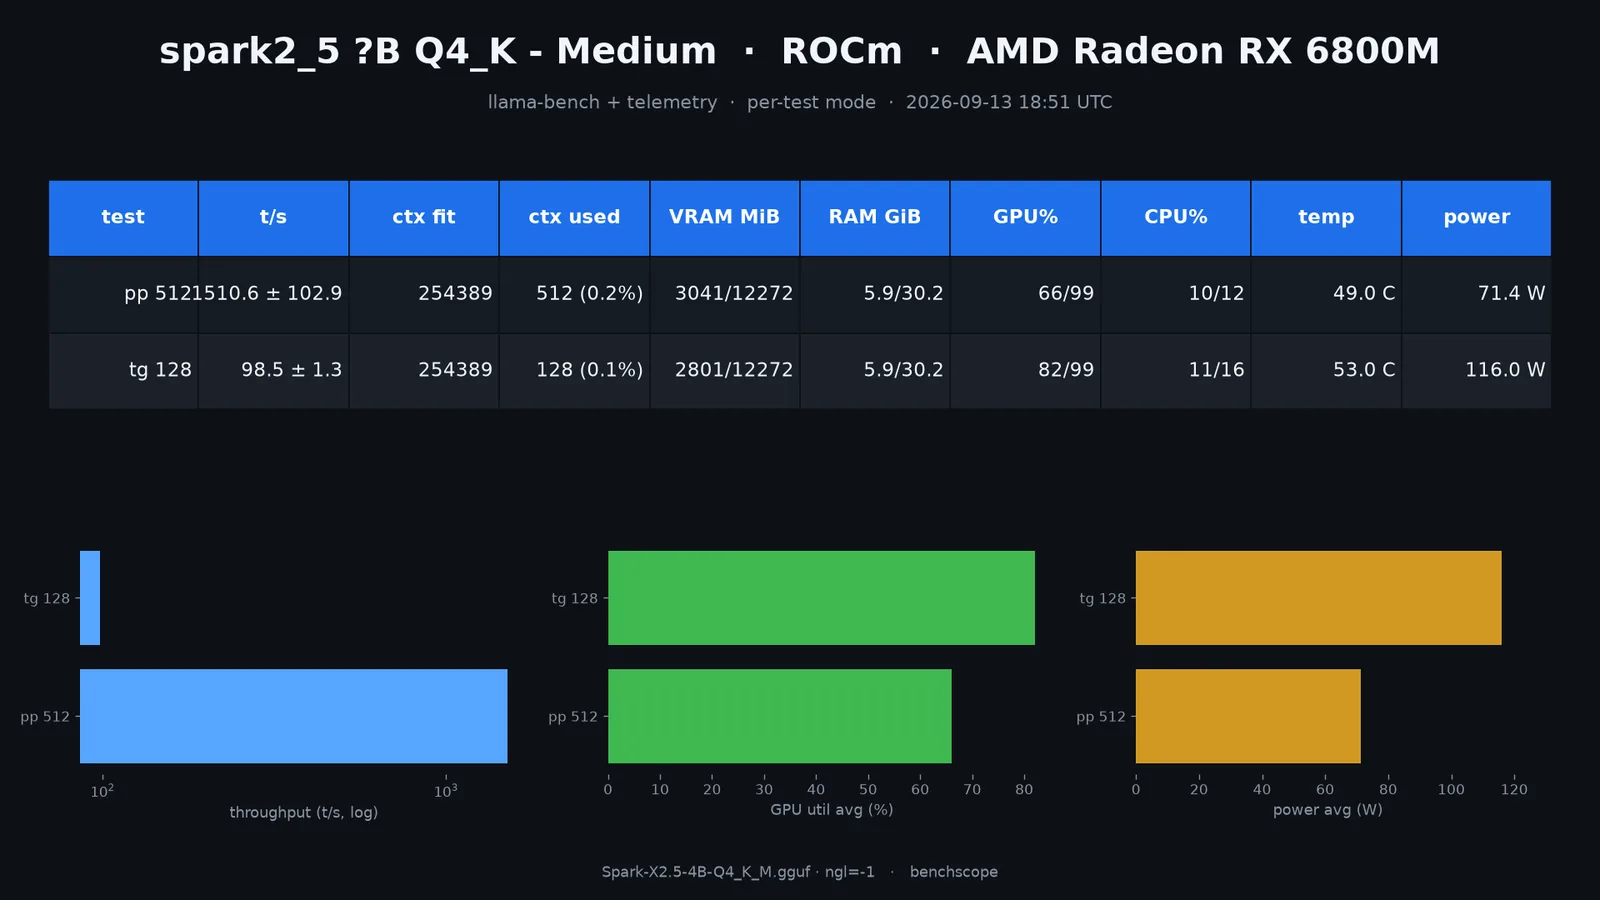
Prompt eval          474.4 ± 16.6 t/s  2148.7 ± 214.9 t/s 1510.6 ± 102.9 t/s
Decode (tg)          39.1 ± 0.2 t/s    67.4 ± 0.5 t/s     98.5 ± 1.4 t/s
Context fit (est.)   101,673 tok       206,244 tok       254,389 tok
VRAM used            8461 / 12272 MiB  4736 / 12272 MiB  3041 / 12272 MiB
GPU util avg         82–89%            64–85%            66–82%
Temp max             62 °C             57 °C             53 °C
Power avg (decode)   120.7 W           101.5 W           116.0 W
Takeaway: there is no single winner. Q8_0 owns prompt processing (4.5× BF16) but with worrying run-to-run variance (±215 tok/s – re-test before trusting it). Q4_K_M owns decoding (2.5× BF16) and carries the biggest context budget (254K vs 101K) in under 3 GB of VRAM. BF16 is third everywhere while running the hottest. The surprise is that quantizing up from Q4 to Q8 buys prompt speed but costs decode speed – prompt eval is compute-bound (dequant cost matters) while decode is bandwidth-bound (bytes per weight matter).
The proof – run cards
Quality check – one tough prompt, three quants
Speed is only half the story, so all three faced the same adversarial prompt (greedy decoding, seed 42, reproducible): a multi-step wattage calculation with an exact-answer format, a records-to-JSON transform with a strict schema, and a median() function written from scratch with sorted() banned. Each output was executed and checked, not eyeballed.
Quality              BF16     Q8_0     Q4_K_M
─────────────────────────────────────────────────
Math ($9.46)         PASS     PASS*    PASS
Exact JSON           FAIL     PASS     PASS
Code runs (5.5)      PASS     PASS     PASS
Generation speed     36 t/s   59 t/s   82 t/s
Takeaway: BF16 – the "best" quant – is the only one that never emits the JSON transform, while Q4_K_M matches it task-for-task at more than twice the speed. Two honest caveats: the deliberately contradictory "output ONLY" instructions make every quant ramble (none finishes in 1024 tokens – budget 4096 for tests like this), and Q4's code leans on the .sort() method, which honours the letter of the ban more than its spirit. Strictly speaking, Q8_0's $9.46 never stands on its own line – it writes "So final answer: ANSWER: $9.46" – so its math PASS carries an asterisk for format.
What broke along the way
unknown model architecture: 'spark2_5'– my llama.cpp checkout predated the architecture. Fix:git fetch+ fast-forward to a build containing upstream#27868(Spark2_5 support), thencmake --build build --target llama-bench llama-cli -j16. No reconfigure needed.libhipblas.so.3: cannot open shared object file–/opt/rocm/libis not on the loader path. Workaround is theLD_LIBRARY_PATHexport; benchscope now injects it into the bench subprocess itself.- Verbose reasoning – this model family thinks out loud at length, so quality runs need a generous
-nbudget even for short answers.
Appendix – the exact build on this machine
For completeness, here is the ROCm build every number above came from (ROCm 7.15, CMake 4.2.3 – targeting gfx1031, the RX 6800M, only, which keeps compile time sane):
git fetch origin master && git merge --ff-only origin/master
# 5f436dddb – first build with spark2_5 support (upstream #27868)
cmake -B build -DCMAKE_BUILD_TYPE=Release \
  -DGGML_HIP=ON -DGPU_TARGETS=gfx1031 -DBUILD_SHARED_LIBS=ON
cmake --build build --target llama-bench llama-cli -j16
Sanity-check that the new architecture loads before benchmarking:
export LD_LIBRARY_PATH=/opt/rocm/lib:$LD_LIBRARY_PATH
./build/bin/llama-bench -m ~/models/Spark-X2.5-4B.gguf -p 64 -n 0 -r 1 -o json
If you see unknown model architecture, your checkout is older than the model – update first, then rebuild. (benchscope injects the ROCm library path into the bench subprocess itself, so day-to-day runs skip the export.)
Bottom line
On a 12 GB RX 6800M, Q4_K_M is the Spark-X2.5 quant to run: ~98 tok/s decode, a 254K-token context budget, 53 °C, and quality on par with full precision. Pick Q8_0 only if your workload is prompt-heavy and you can tolerate its variance. Skip BF16 unless you need bit-exact weights – it costs 3× the VRAM for third place and, on my test, dropped a formatting task both quants passed. Full method, telemetry and the measuring tool: benchscope on GitHub →